Jatan
What it is
A damage-mapping tool that tells disaster teams which road or bridge to repair first.
Who it's for
Rapid-assessment teams at disaster agencies, who receive damage reports through many channels at once.
How it works
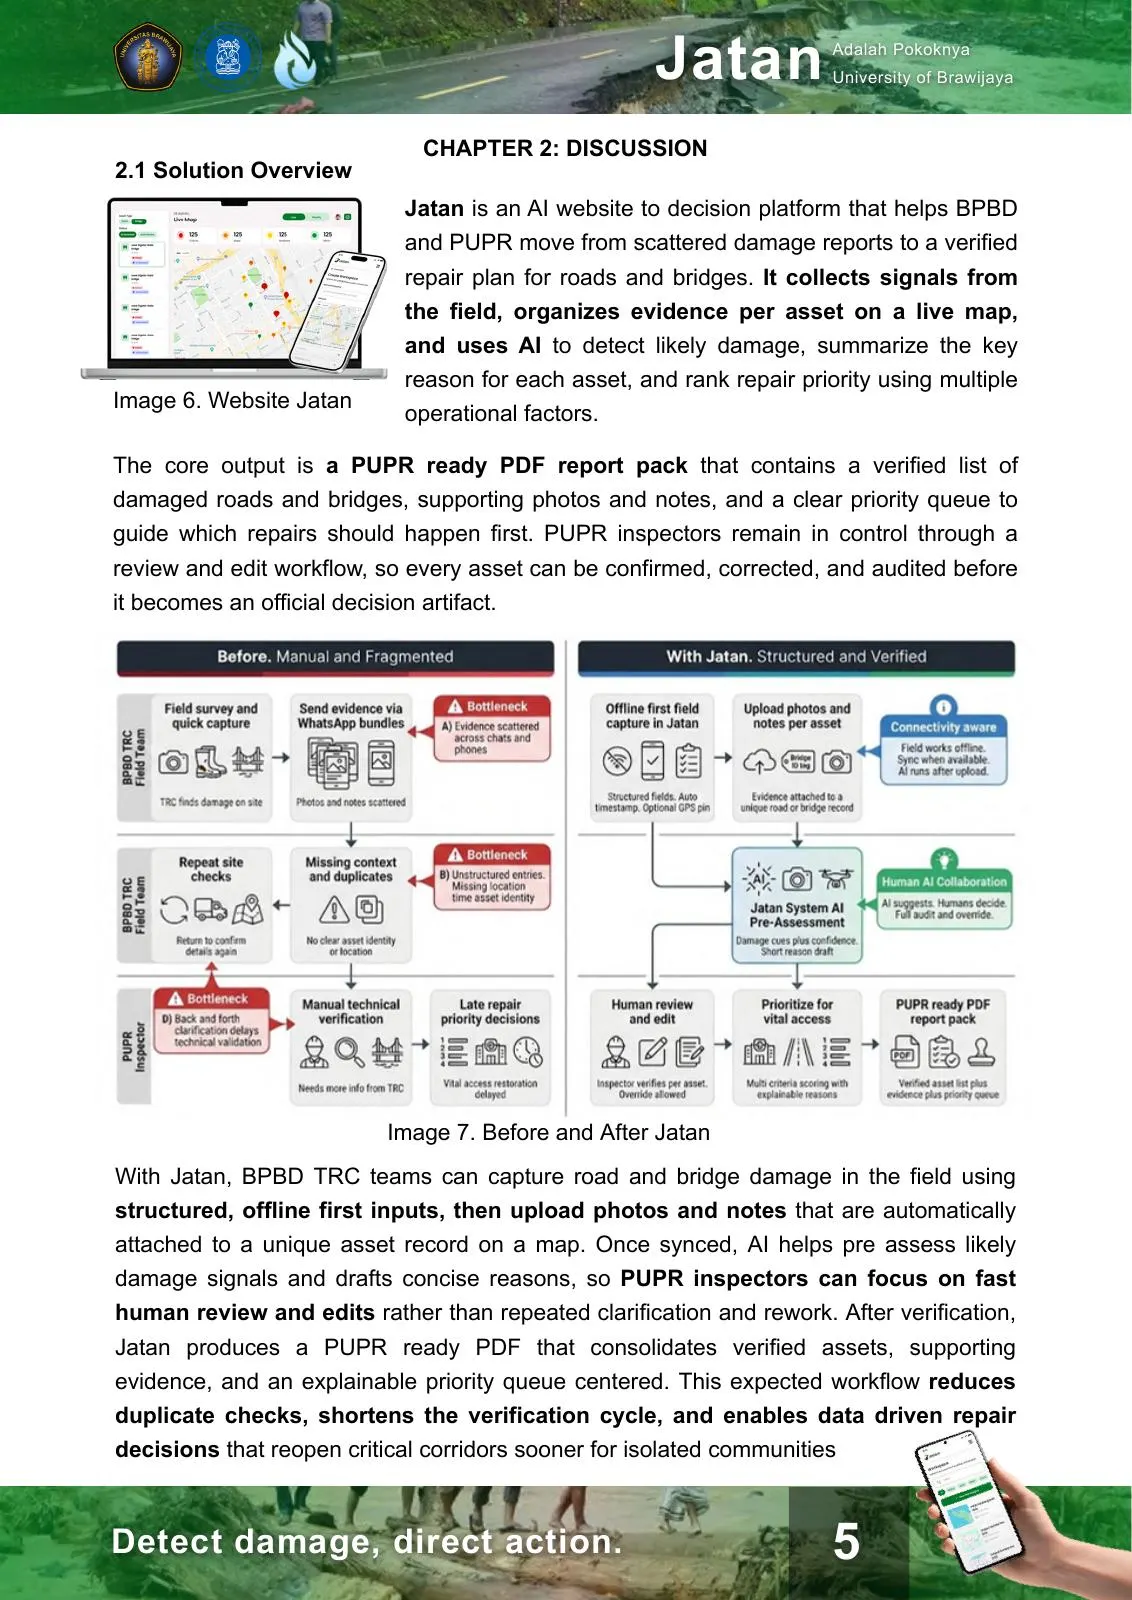
Drone or field photos are scored by AI for severity and passability, then ranked into a repair queue that shows what each repair unlocks.
The problem
Context
In late November 2025, flash floods hit Sumatra, where I grew up and where my family still lives. More than 4,000 infrastructure points were damaged, including 734 bridges, and whole communities became unreachable.
Damage reports reach disaster agencies through many channels. Deciding which road or bridge to fix first was slow and hard to justify.
What we learned first
The bottleneck was agreeing on the order of repairs. A ranked list without a reason gets argued with; a ranked list that shows who gets reached gets acted on.
Constraints
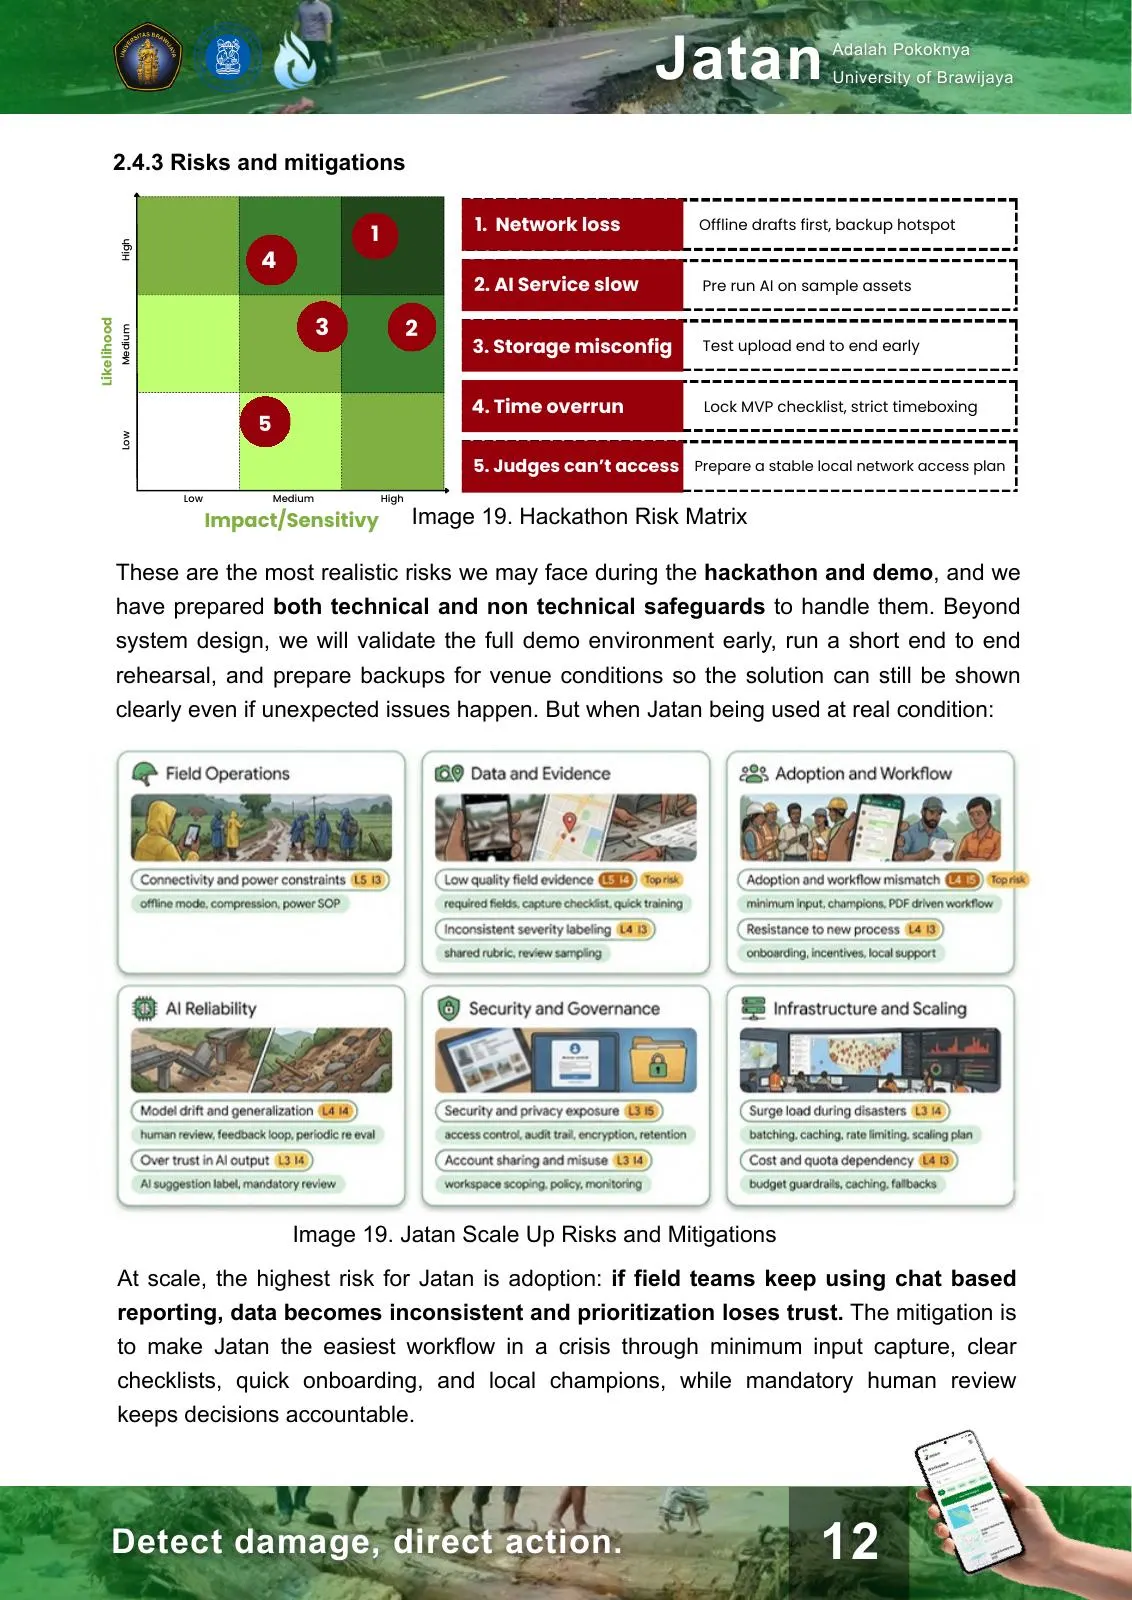
- Field teams often have no signal
- Officials must be able to defend every priority call
- AI output must stay editable by humans
My role
Richard on this project
Team lead & Product Manager
Product skills
- Workflow mapping
- Personas
- PRD writing
- Prioritisation logic
- Human-in-the-loop AI
Project skills
- Team leadership
- Demo target setting
- Pitching
As product manager
- Mapped the rapid-assessment workflow and the personas
- Wrote the PRD, including the prioritisation logic
- Kept a human decision on top of every AI verdict
As project manager
- Set the 24-hour demo target the team built toward
- Led a team of four: PM, AI, engineering, design
- Owned the final pitch at the national finals
Not my role
- Model training and routing code: owned by the AI and engineering teammates
The work
Key decisions & trade-offs
- Decision 01
Show what a repair unlocks
Tapping a priority marker reveals the hospitals, posts and population that become reachable if that one asset is repaired, computed on the road graph, plus a one- or two-sentence reason.
Trade-off More work than a plain score, but it turns a model output into a decision people can defend.
- Decision 02
Humans stay in the loop, on purpose
Every AI result is editable and moves from 'AI generated' to 'Done review'. We deliberately showed no confidence score, so reviewers judged the evidence itself.
Trade-off Slower than full automation, but trustworthy in a context where a wrong call costs lives.
- Decision 03
Offline for input, online for AI
A PWA lets field teams capture photos, pins and asset names offline as queued drafts. AI runs when the connection returns. Offline inference was explicitly out of scope.
Trade-off Field reports wait for a signal before AI scores them, and none of them get lost.
How it was built
Two modes: Live Mapping (drone or field photos → AI severity, passability and damage type) and Prioritizing (ranked repair queue with reasons and the 'unlock' view). Demo target: one flood workspace, 4-5 assets, ≤2 minutes of AI per batch.
- Severity: light / moderate / heavy / cut off
- Passability: 4-wheel / 2-wheel / impassable
- Note: no confidence display (decided)
- Field photoOffline draft allowed
- AI assessmentSeverity, passability, damage type
- Human reviewEditable, no confidence score
- Ranked repairsWith a 1-2 sentence reason
- Unlock viewWho gets reached if fixed
From the work itself
The result
- 3rd
- place, Hackvidia national finals
- 2
- modes: map the damage, then decide the order
What I'd do differently
Next time I'd validate the prioritisation weights with someone who has run a real rapid assessment, before the demo.